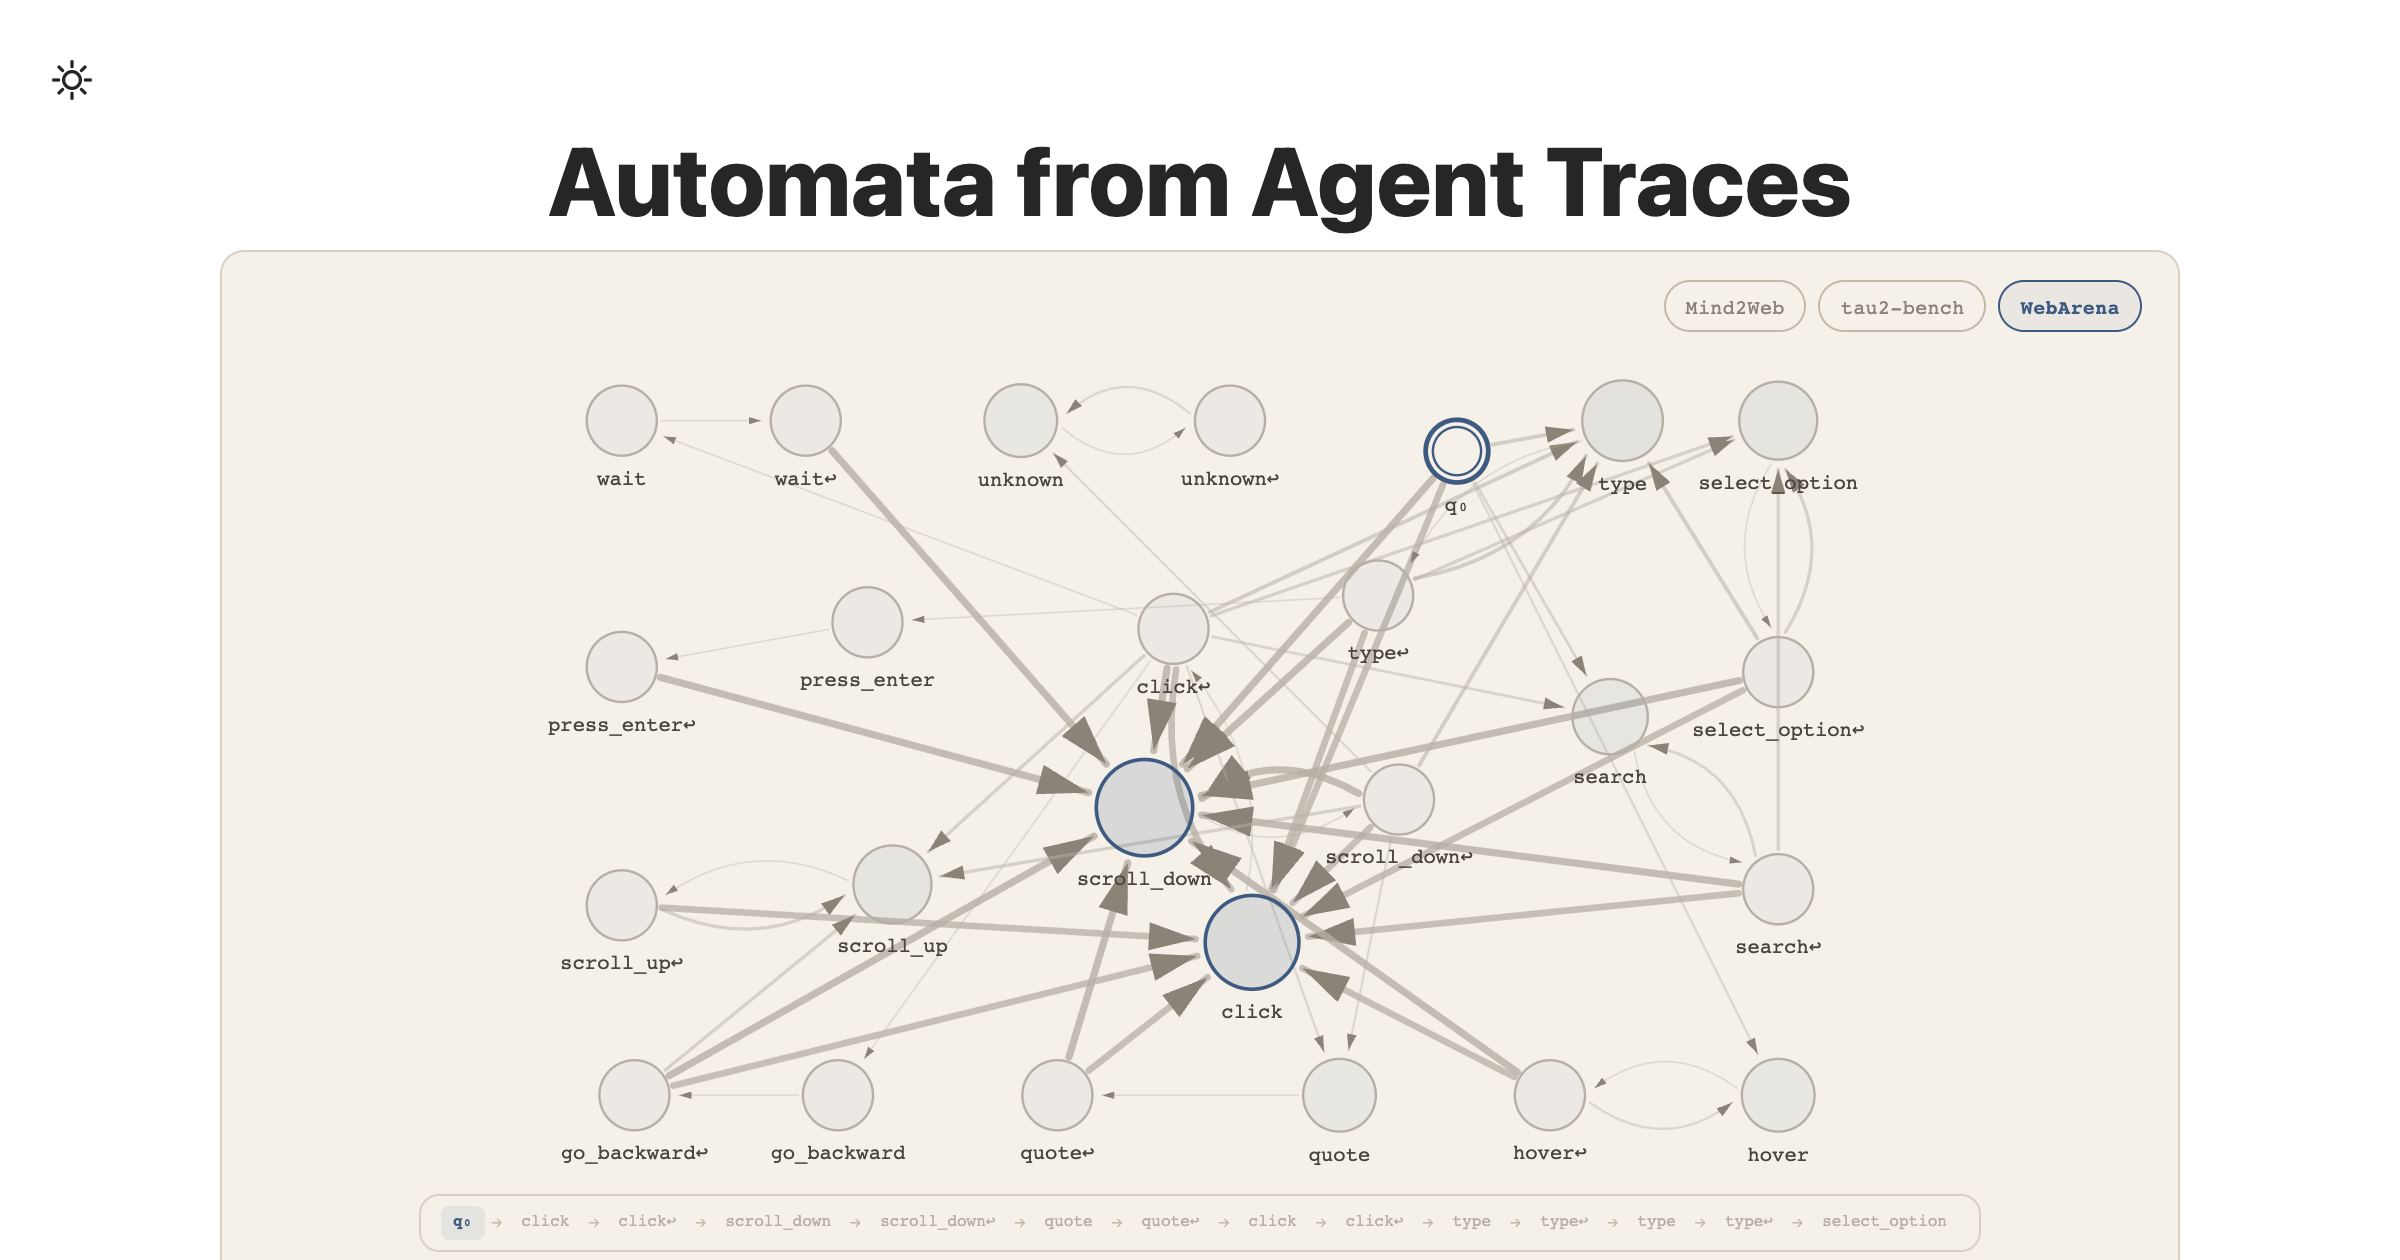
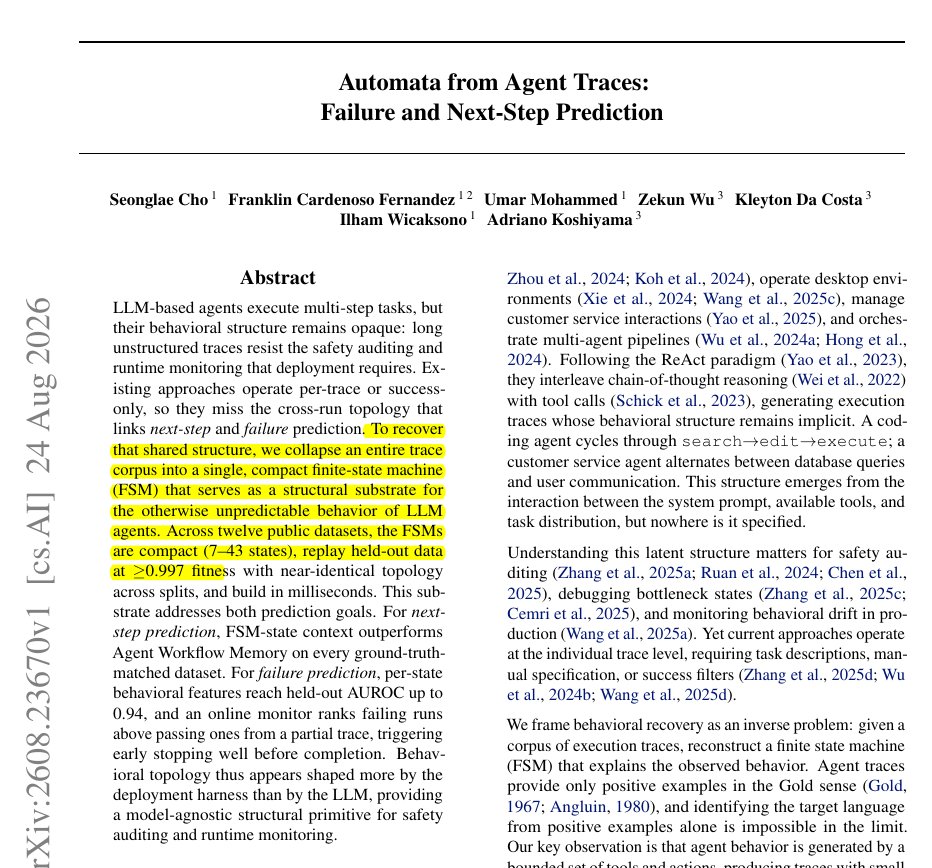
Agent State Graph Verifying your browser | OpenReviewhttps://openreview.net/forum?id=1cprFkvFT0articleAutomata from Agent TracesAutomata from Agent Traces: compact finite-state machines extracted from LLM agent traces for failure prediction, next-step prediction, and runtime monitoring.https://seongland.com/article/asgVedansh — backend & AI engineerStorage engines, network stacks, real-time media — from scratch, grounded in the papers. AI/ML systems.https://www.vedanshh.com/blog/context-engineeringconcurrent work from Alergia arxiv.orghttps://arxiv.org/pdf/2608.14352newsRohan Paul on Twitter / XDifferent LLMs may behave more similarly inside an agent harness than their raw traces suggest.LLM agents can produce massive traces while following a surprisingly small behavioral graph, and that graph can predict both what happens next and when a run is failing.Basically… pic.twitter.com/Iv0AB8jK1V— Rohan Paul (@rohanpaul_ai) September 2, 2026 https://x.com/rohanpaul_ai/status/2094962129552232465// Automata from agent traces // How much of your agent's behavior comes from the model, and how much from the harness you wrapped around it? New work collapses an entire corpus of agent traces… | DAIR.AI// Automata from agent traces // How much of your agent's behavior comes from the model, and how much from the harness you wrapped around it? New work collapses an entire corpus of agent traces into a single compact finite-state machine. Across twelve public datasets the induced machines run 7 to 43 states, replay held-out data at 0.997 fitness with near-identical topology across splits, and build in milliseconds. FSM-state context beats Agent Workflow Memory on every ground-truth-matched dataset for next-step prediction. Per-state behavioral features reach held-out AUROC up to 0.94 for failure prediction, and an online monitor ranks failing runs above passing ones from a partial trace, triggering early stopping well before completion. The authors suggest that behavioral topology gets shaped more by the deployment harness than by the LLM underneath it.https://www.linkedin.com/posts/dair-ai_automata-from-agent-traces-how-much-activity-7498796241640652800-sXAXelvis on Twitter / XAnother good paper. Interesting finding on the benefits of the agent harness. https://t.co/12iaK1sZ7J— elvis (@omarsar0) August 27, 2026 https://x.com/omarsar0/status/2093051230197043245HHMM Hierarchical states for hierarchical goalarxiv.orghttps://arxiv.org/pdf/2609.14605ControlRL: language model inference as Markov Decision Process Control Reinforcement Learning: Interpretable Token-Level Steering...Sparse autoencoders (SAEs) decompose language model activations into interpretable features, but existing methods reveal only which features activate, not which change model outputs when...https://arxiv.org/abs/2602.10437 Predictive Coding





 Seonglae ChoSeonglae Cho