Seonglae Cho
Randomness
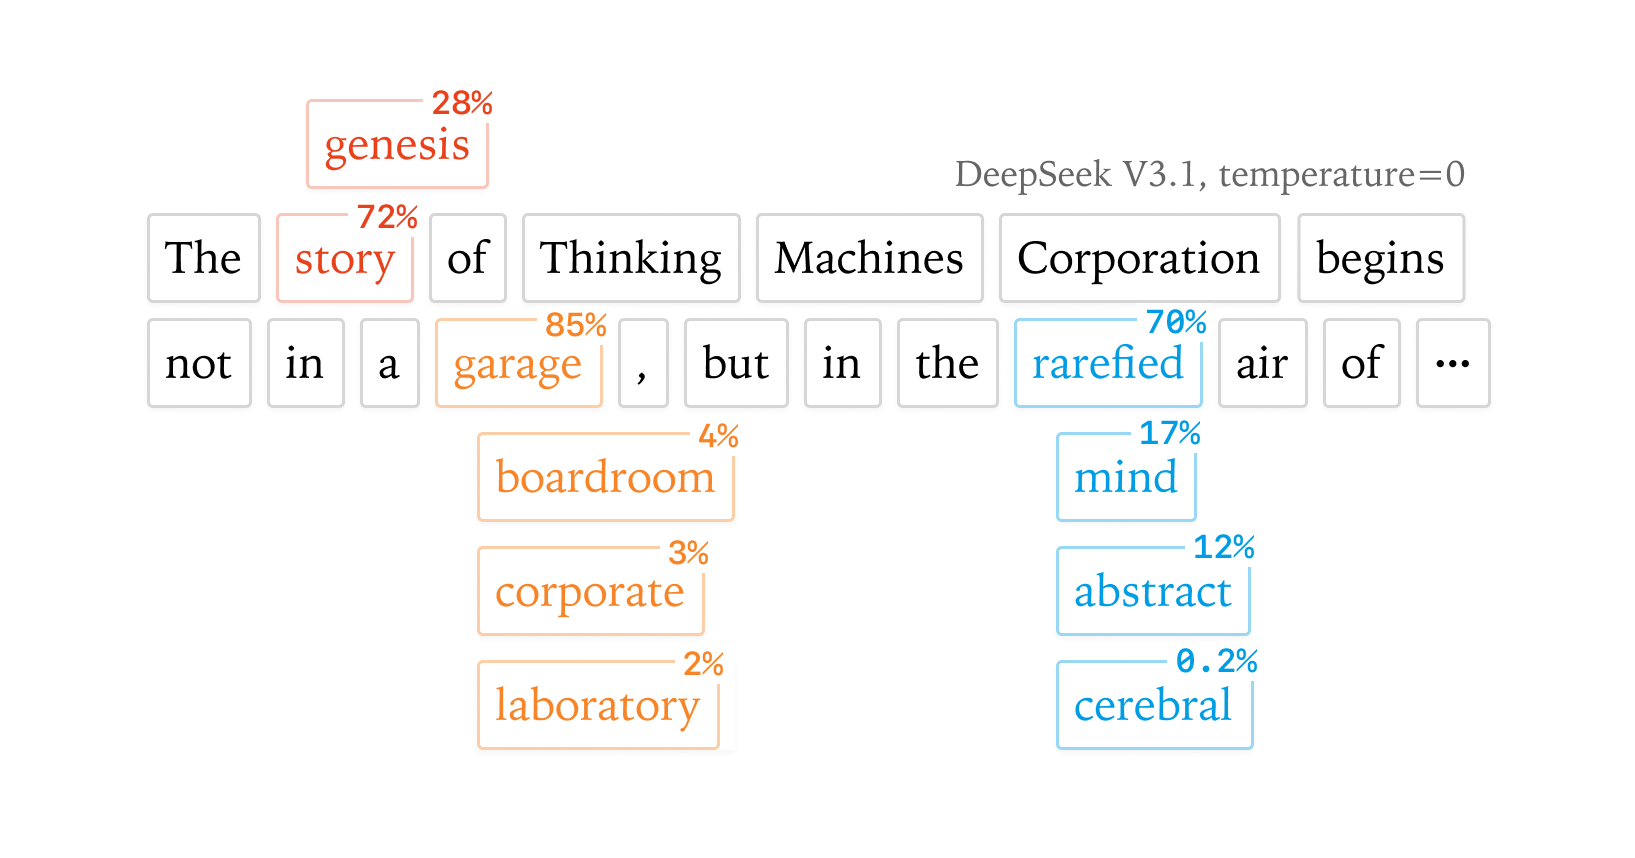
Temperature is only applied to output logit softmax
- When T=0, it selects the token with highest probability (deterministic, greedy decoding)
- When T approaches infinity, probability distribution becomes uniform, increasing randomness
Even with temperature = 0, you can still see nondeterminism in LLM inference because of batching. When the batch size changes, the GPU kernel may evaluate the same mathematical expression in a different order. For example, batch size 1 vs. batch size 2048 can lead to different tile sizes, different reduction orders, different Tensor Core instruction choices, and different parallelization strategies.
The main reason is not simply “GPU threads finish in random order so atomic-add ordering changes”; more precisely, the reduction strategy selected by the kernel itself can change with batch size. Because floating‑point arithmetic is not associative, changing the computation order can change results at the bit level, which can then cascade into different generated tokens.
RMSNorm, matmul, and attention all involve reductions. If the reduction order depends on the batch size, batch invariance breaks. The solution is to use a batch-invariant kernel (i.e., enforce a reduction strategy that does not change with batch size).