 Seonglae Cho
- d is model embedding dimension
- i is index of embedding vector
- p is token position of input text
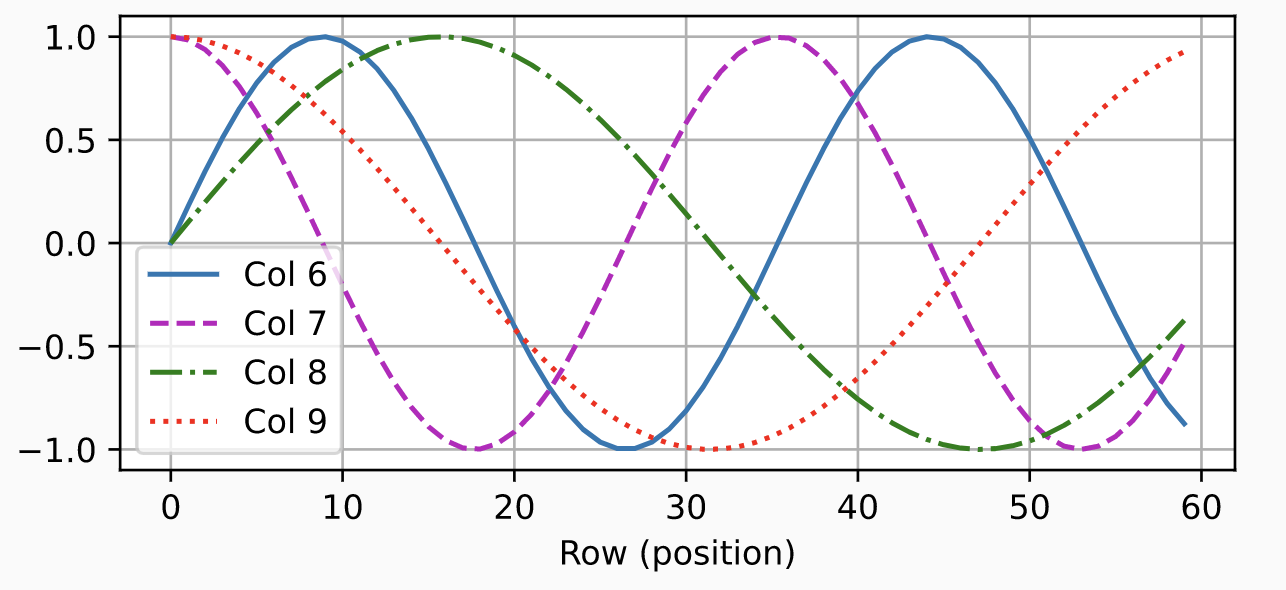
Overall, different frequencies are assigned to each position to make them recognizable, and using different even/odd functions (sine/cosine) creates phase differences that make each position distinctly identifiable
Key points of the formula below
- Designed to consider exponential positions according to embedding dimension
- Separates high and low frequencies to distinguish positions through frequency

In theory, it can distinguish exponential positions relative to the model embedding depth
Ultimately, attention weights fit to this mathematical position encoding. The design of this function only needs to ensure that embeddings are distinguishable from each other