Seonglae Cho
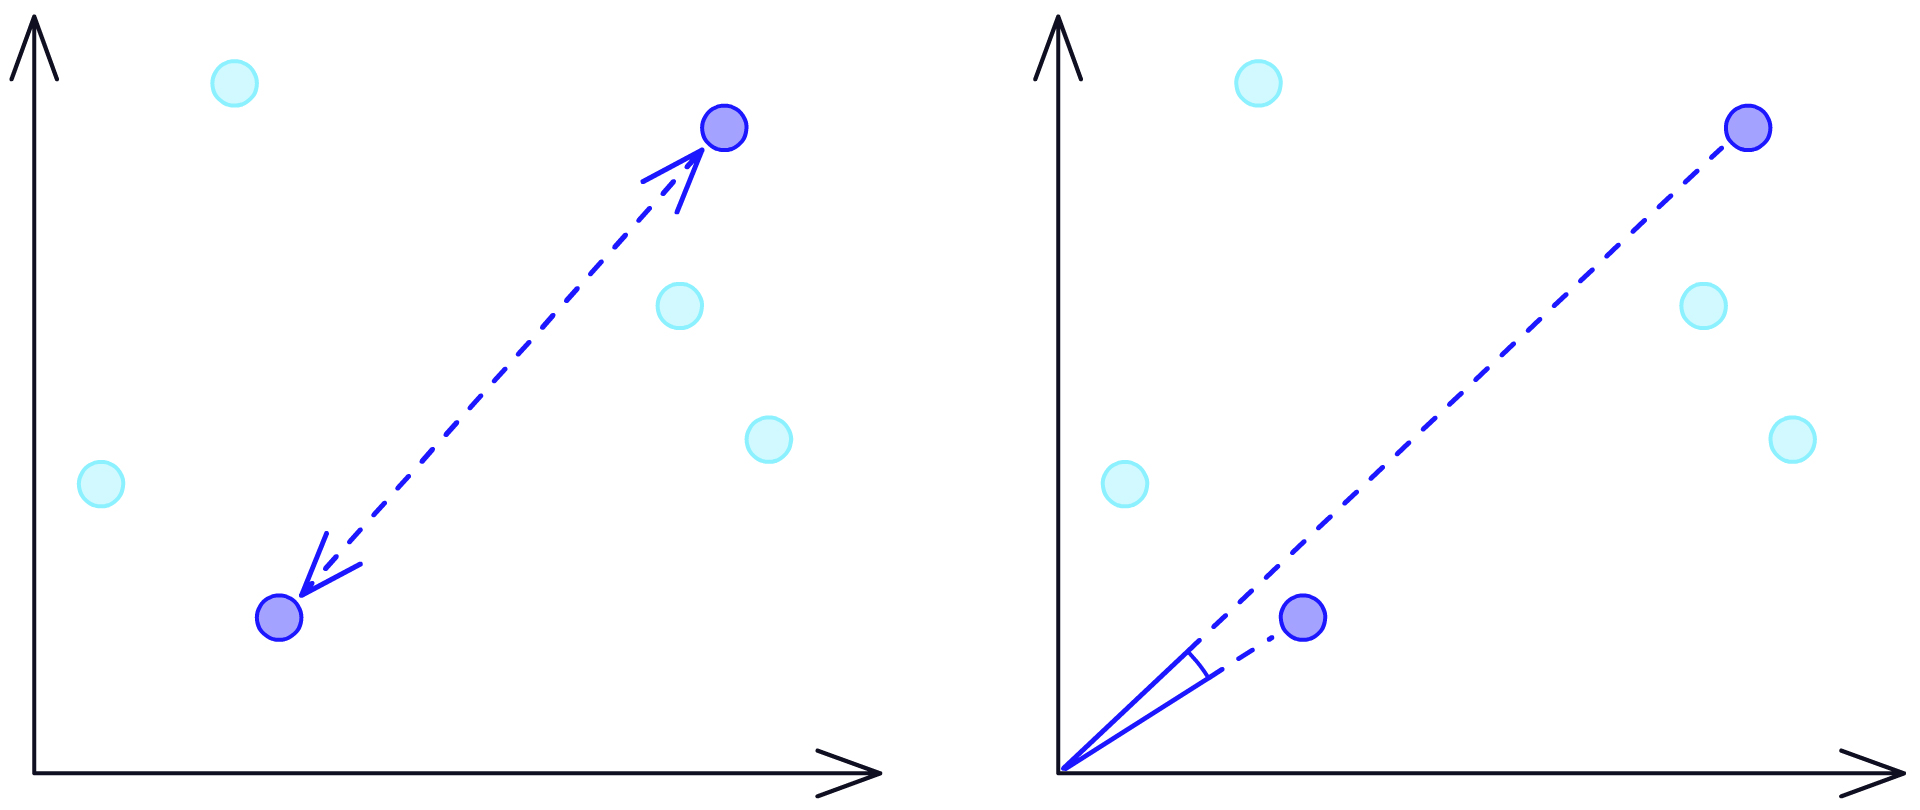
Vector Similarity
Bridges the gap between Information retrieval and Memory retention in LLM
Useful traditional database is Postgres Vector or Redis Search
Bottleneck is Disk System IO capacity
Vector Databases
Vector Database Notion
CPU optimized turbopuffer HNSW 대신 클러스터 기반 SPFresh, WAND 대신 벡터화된 block-max MAXSCORE를 사용해 예측 가능한 순차 연산을 확대
Architecture



We should consider embeddings as derived data (like DB Index) instead of independent data