

 Seonglae Cho
Pattern is important
Window attention, where only the most recent KVs are cached, is a natural approach

Sparse Attentions
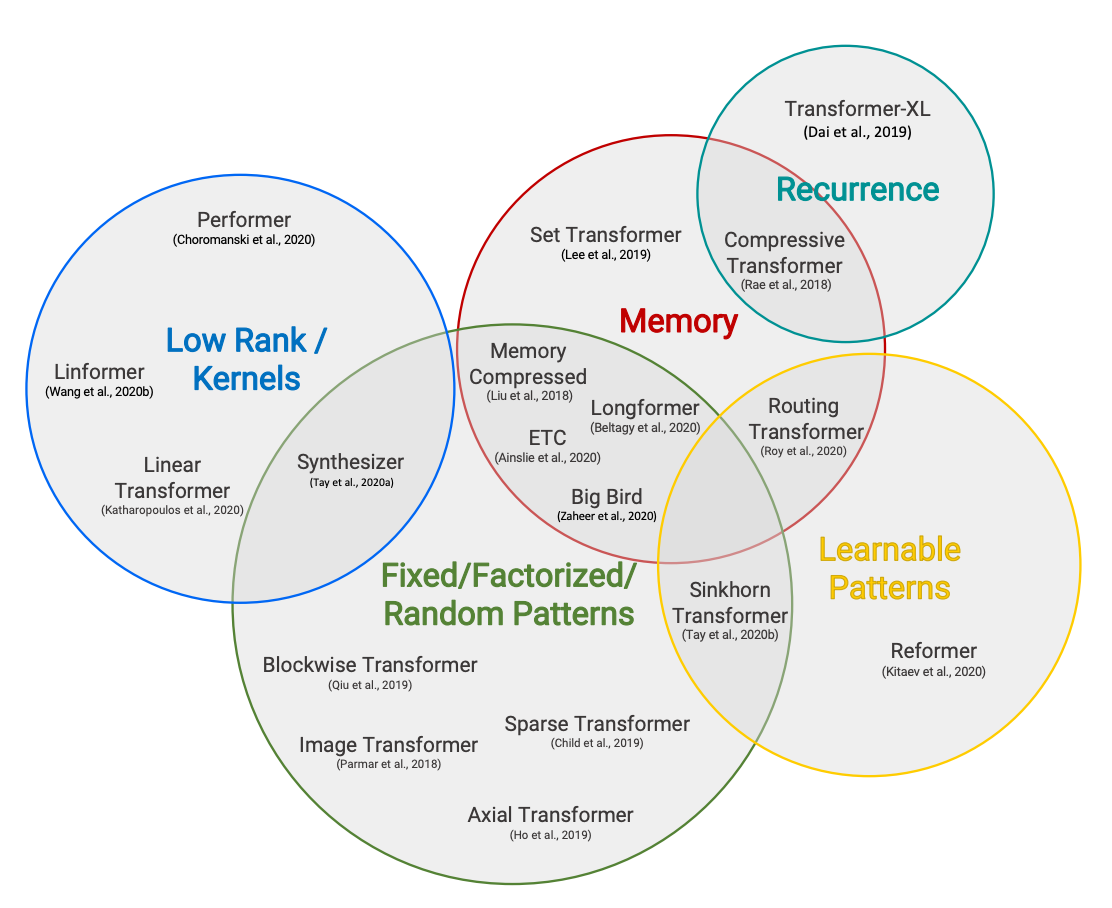
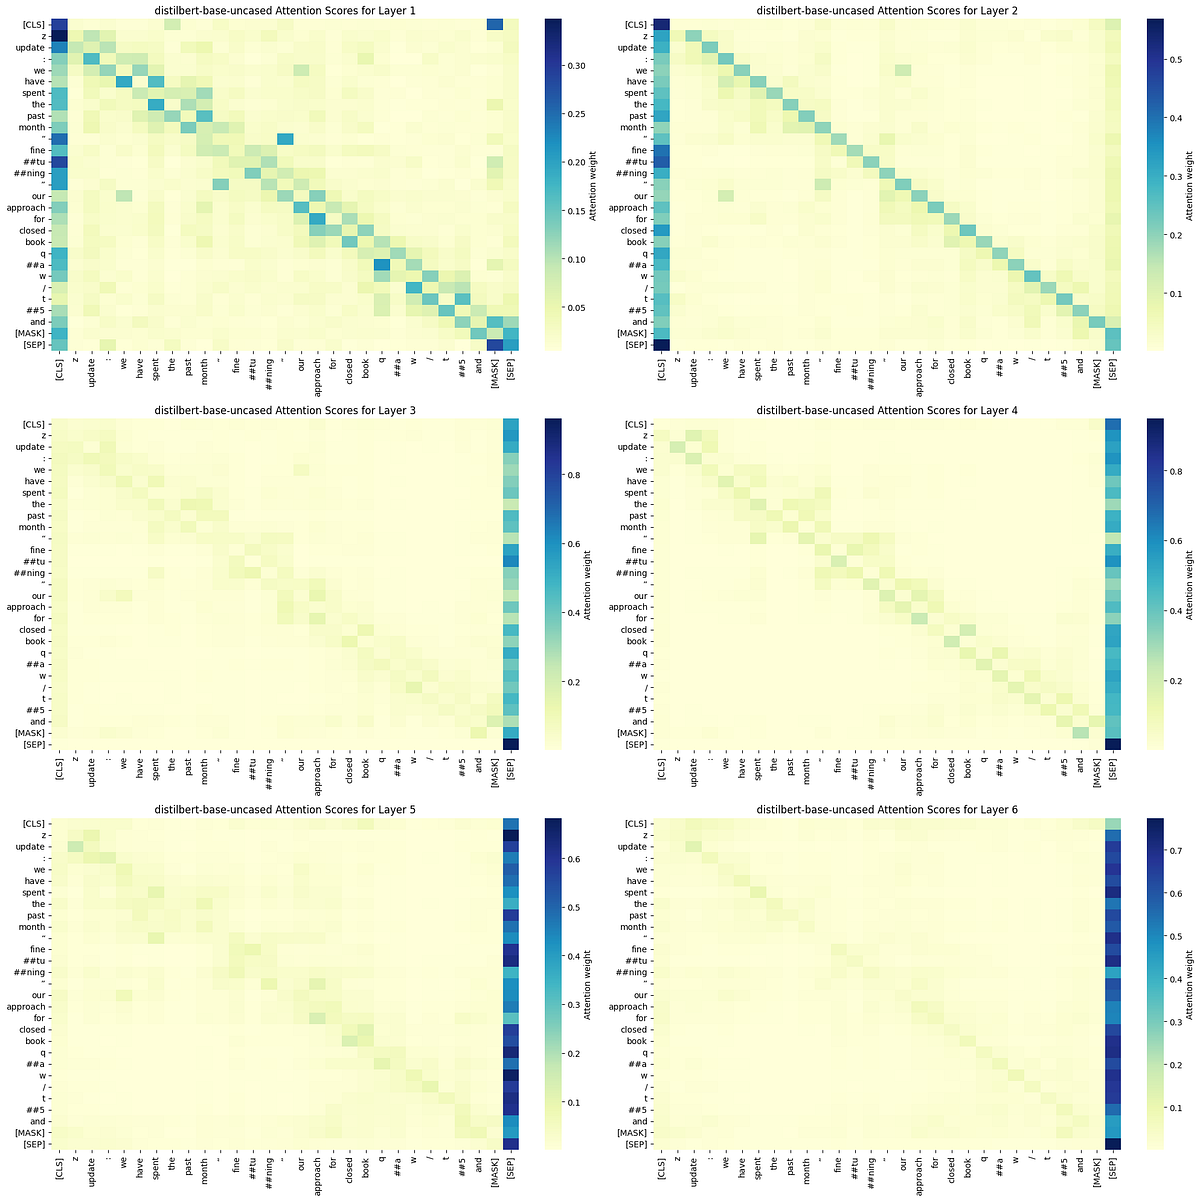
Sparse attention indexer for GLM 5.2

IndexCache
Based on the observation that adjacent layers in sparse-attention models select 70–100% of the same tokens, IndexCache runs its own indexer only on Full layers, while the remaining Shared layers reuse the top‑k indices from the nearest Full layer. The training-free variant uses greedy search to decide which layers keep an indexer, so no weight updates are needed. The training-aware variant trains the indexer with a multi-layer distillation loss. On a 30B model, it removes 75% of indexer computation and achieves 1.82× faster prefill and 1.48× faster decoding. Patches for SGLang and vLLM are also provided.
KV Cache Transform Coding (KVTC)
This applies principles similar to JPEG compression to LLM memory, combining a pipeline of PCA-based feature decorrelation, adaptive quantization, and entropy coding. The PCA basis matrix is computed once on a calibration dataset and can then be reused for all subsequent inference.