

 Seonglae Cho
Transformer Interpretability
A transformer starts with a token embedding, followed by a series of residual blocks, and finally a token unembedding
MLPs store factual information and Attention performs pattern matching. Since in transformer models, MLPs are token-wise operations while attention is an inter-token operation
Both the attention and MLP layers each “read” their input from the residual stream (by performing a linear projection), and then “write” their result to the residual stream by adding a linear projection back in.
- Transformers have an enormous amount of linear structure.
- One layer attention-only transformers are an ensemble of bigram and “skip-trigram
- Two layer attention-only transformers can implement much more complex algorithms using compositions of attention heads
When there are many equivalent ways to represent the same computation, it is likely that the most human-interpretable representation and the most computationally efficient representation will be different. Composition of attention heads is the key difference between one-layer and two-layer attention-only transformers
- logit
- token vectot
- embedding matrix
- MLP output
- Attention head
- token unembedding

Fundamentally, if activations in attention appears linearly, then the activation function's non-linearity is a side effect, and like in diffusion models, noise reduction through layers might be the main role.
Reversing Transformer Notion
Attention-only transformers, which don't have MLP layers
Because they had much less success in understanding MLP layers so far (2021)

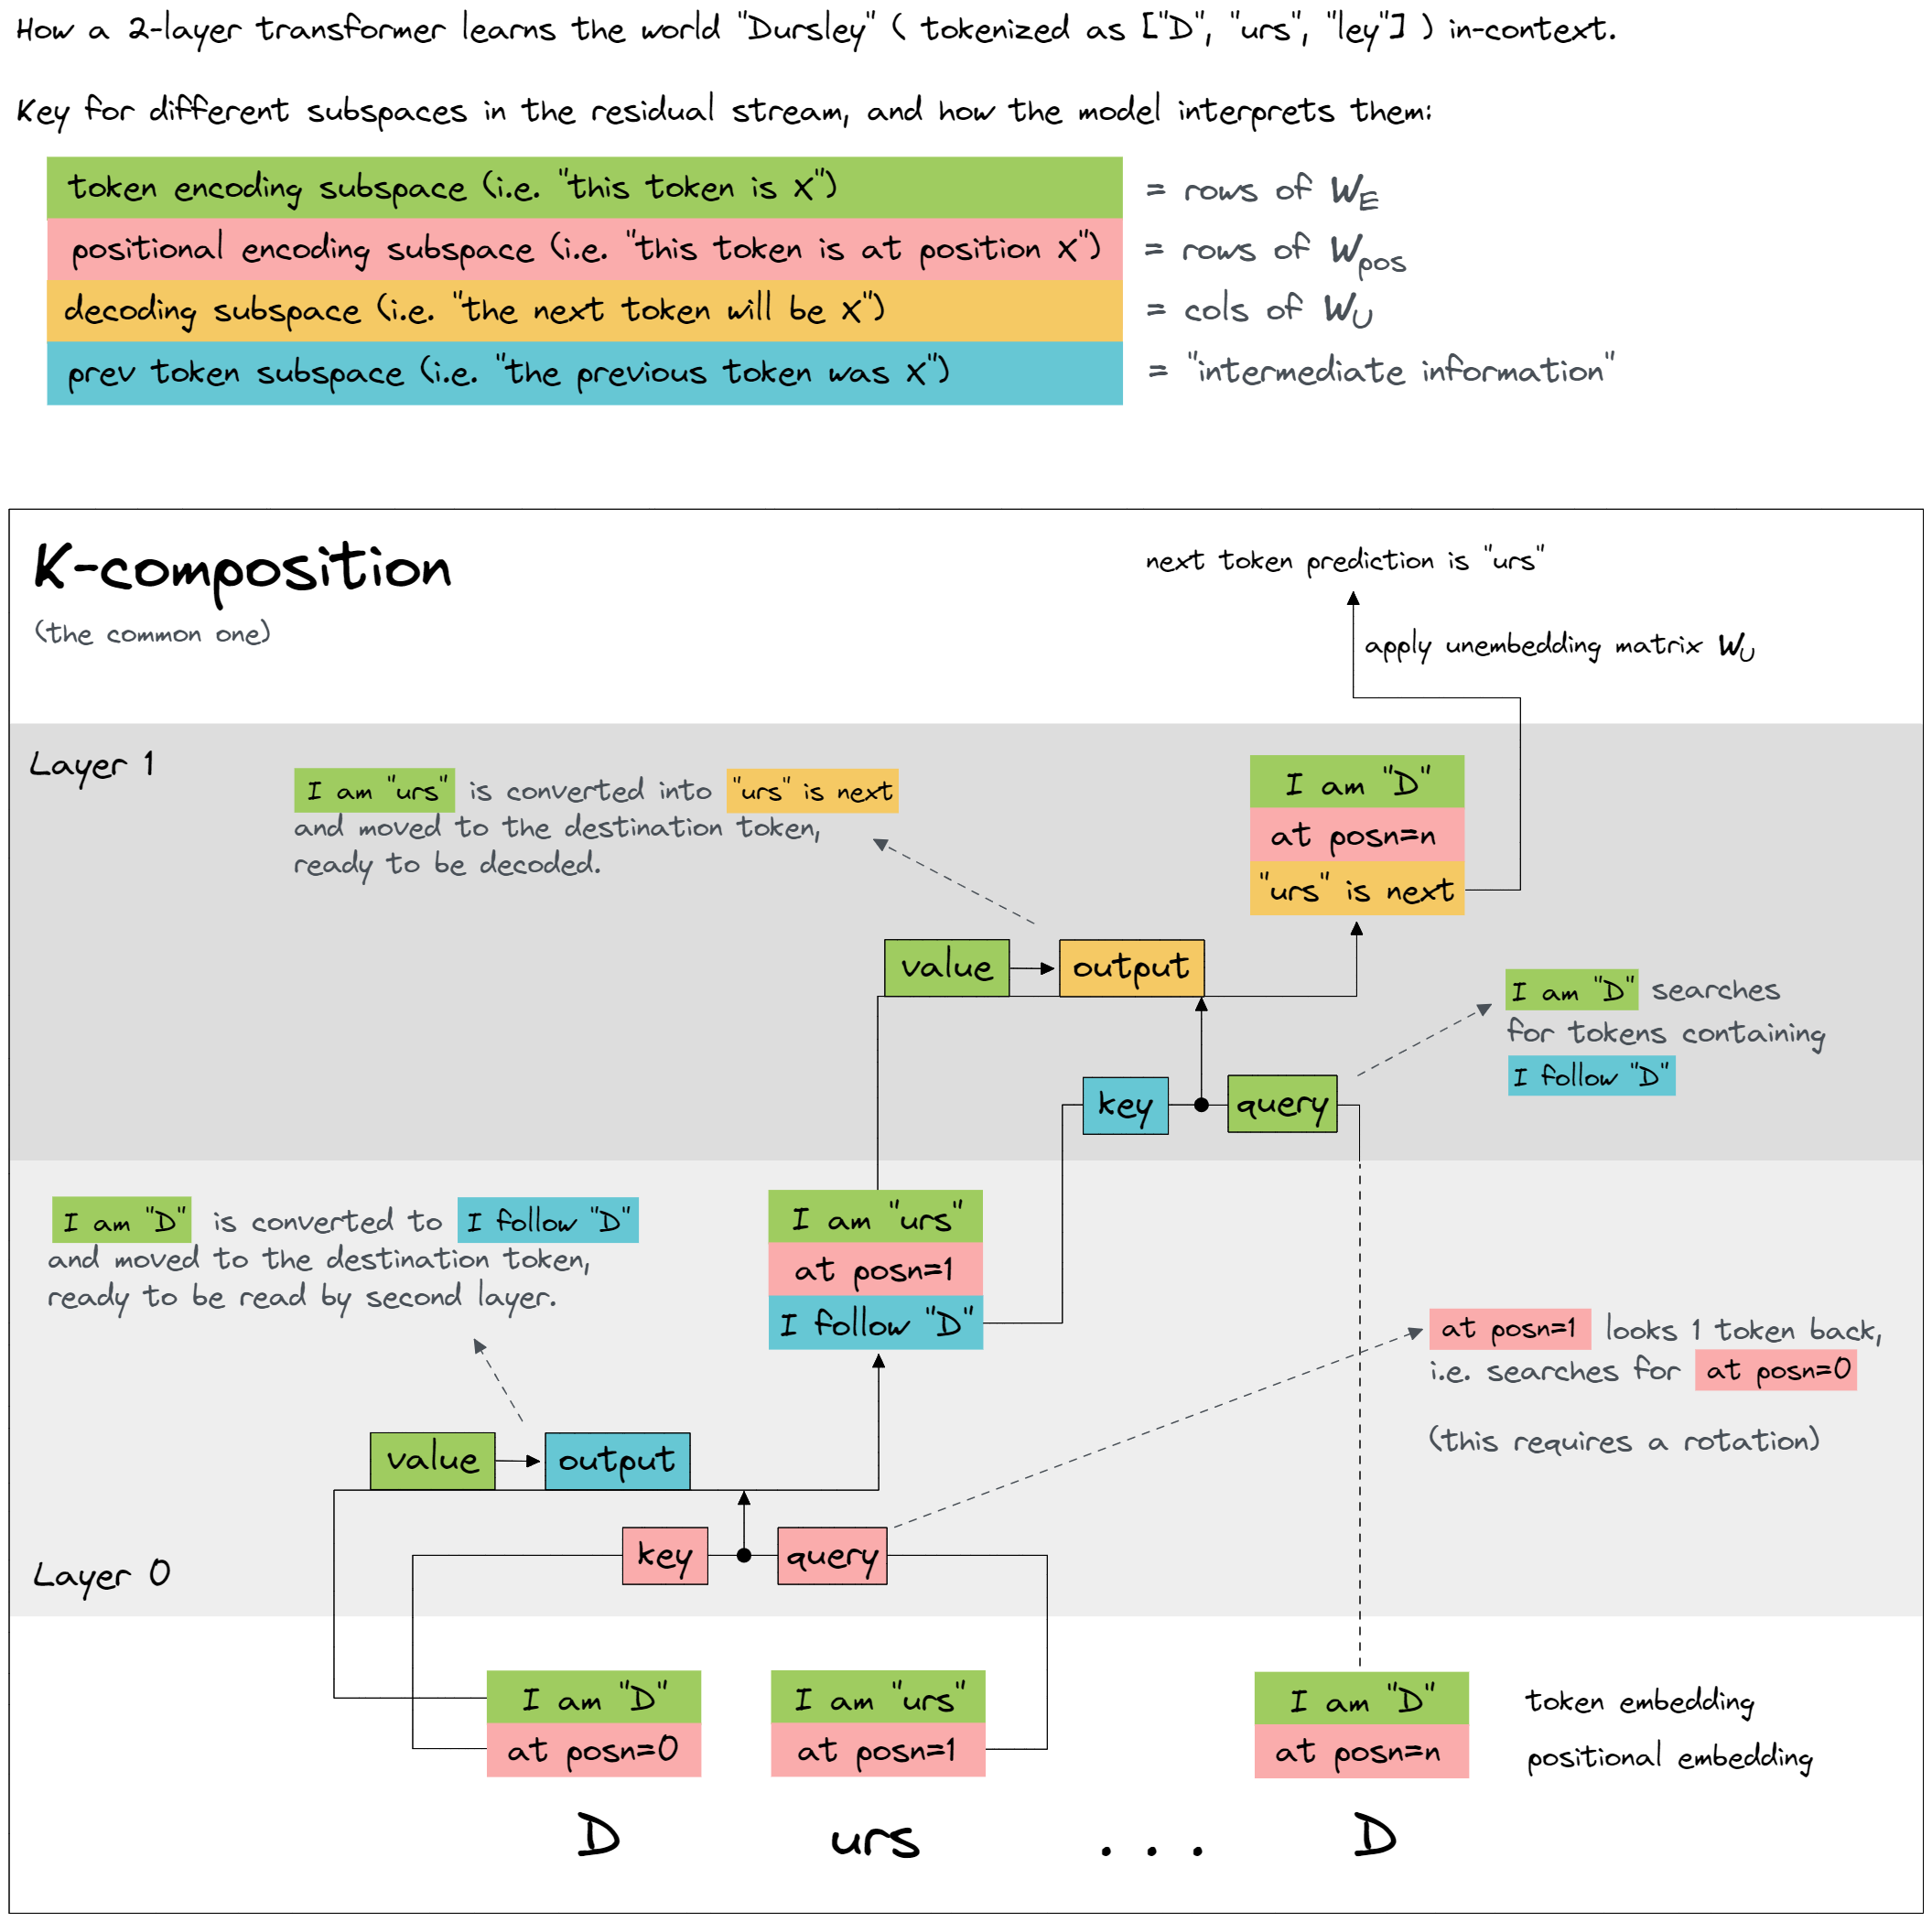
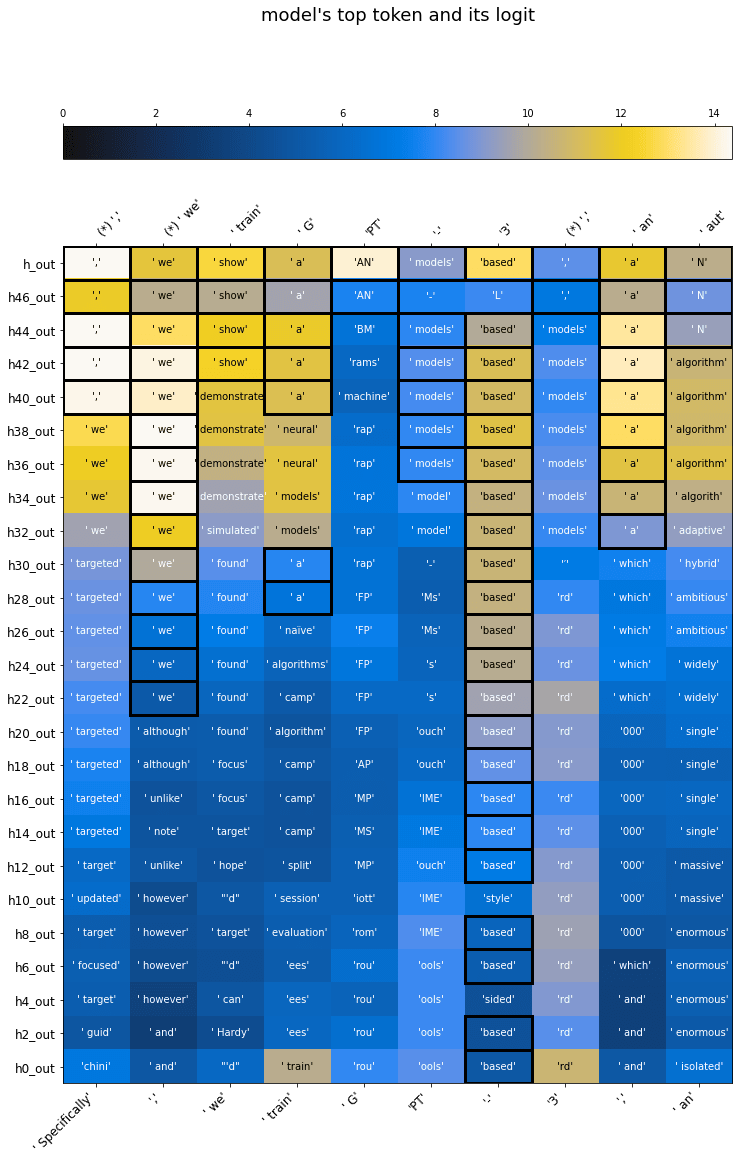
Handcrafting transformer

LLM Training Data is Nonergodic → ICL Bayesian belief updating Belief State
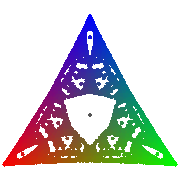
In-context learning is described as the process of inferring which data-generating source is currently active. When predicting data mixed from multiple sources, an internal geometry emerges in which the strength of belief in each source shifts with contextual evidence. This was confirmed in Transformers trained on synthetic data, providing grounds for understanding features as multi-dimensional subspaces rather than single directions.
Transformer Layer Model Layer Scaling
The next layer in a Transformer immediately cancels part of the change made by the previous layer. This selective-correction phenomenon was observed in 5 of 7 model families. A feature found at one layer therefore has to be distinguished as either information that persists into the final prediction or a temporary computation that will soon be erased.

Progressively increasing a model's computational depth during training improves scaling efficiency. A grown 7.4B model reached a CORE score comparable to GPT-3 13B with roughly 20x less training compute.