Seonglae Cho
LLM is quite dumb without context
Extrapolation ability above trained context length is an important issue and this is the weak part of the Transformer Model.
The first appearance was the hacking using Positional Embedding. The trigonometric-based absolute positional encoding worked well by separating frequencies, but there is a problem that it does not work well unless it is data of the length often seen during training because extrapolation does not work.
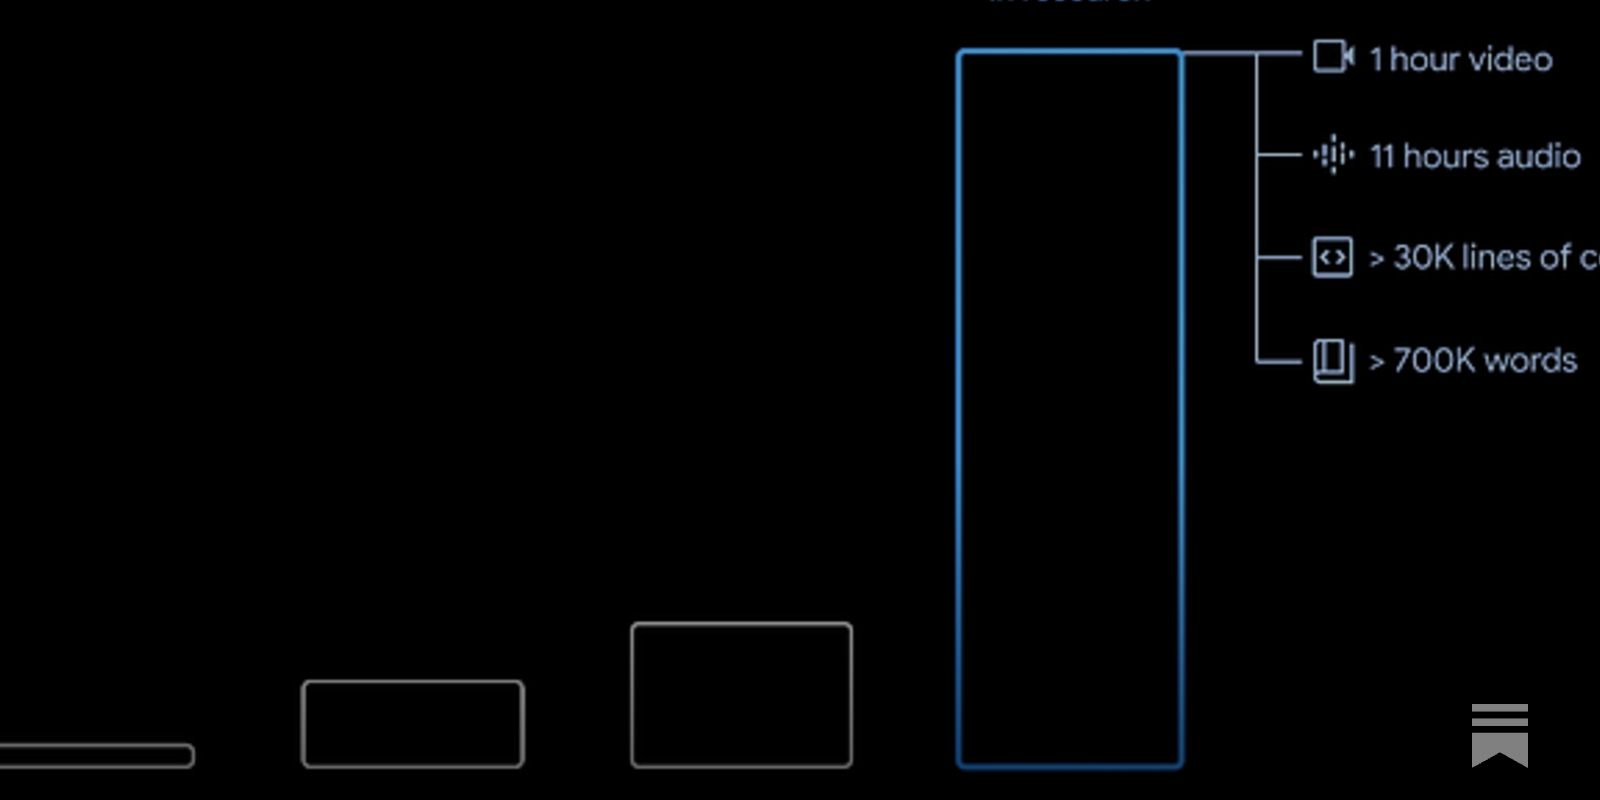
Lost in the middle poured cold water on RoPE’s prospect. It showed that these models, which expanded the context using RoPE interpolation, referenced the beginning and end of the prompt well but did not capture the middle part well. It even stated that performance could be worse than when no data was given at all. Gemini Google is seeking a solution with Ring Attention.
With Reformer and Performer in mind, many efficient transformer structures have been poured out to support long context while reducing the cost of Attention's O(N^2), and there have been some promising things, but in the end, it turned out that the ordinary vanilla attention is the best as the data increases. If there is a lesson that the transformer constantly tells us since it first appeared, it is to follow the rules without tricks.
Language Model Context Notion
Language Model Context Usages